DelftBlue Crash-course for absolute beginners
New course: Command Line and DelftBlue Basics
Want to learn how to use the Linux command line on the DelftBlue?
Every month a crash course for beginners is organised getting you up to speed in only one day! This covers not only the basics on how to work with a command line in Linux but also specifically on how to use these skills on the DelftBlue.
Register now via this link: Linux Command Line Basics Course
Important
DelftBlue is a Linux computer. Basic Linux command line knowledge is a pre-requisite to being able to use DelftBlue! Luckily, the basics of working with Linux can be relatively easily self-taught with online materials. Start with checking out the relevant Software Carpentry courses (the first one is an absolute must if you are a beginner):
Linux command line (more advanced stuff)
Introduction to High-Performance Computing
Furthermore, we periodically organise Linux Command Line Basics training on campus:
Linux Command Line Basics Course
As well as DelftBlue-specific training sessions:
What is a supercomputer?
In essence, a supercomputer is a collection of (large) computing resources: processors (CPUs), graphics processors (GPUs), memory (RAM), hard disks, that are shared with other users. A special type of network makes it possible to use multiple of these resources in a tightly coupled way, i.e., to scale up your applications. A Supercomputer makes it possible to:
- Schedule lots of jobs.
- Do a lot of computational work.
- Use a lot of concurrent processes and threads within a program.
- Run long computations.
- Compute on big data sets.
- Use GPUs, either for computations (if your application/code supports it) or for post-processing/visualisation.
How is DelftBlue organised?
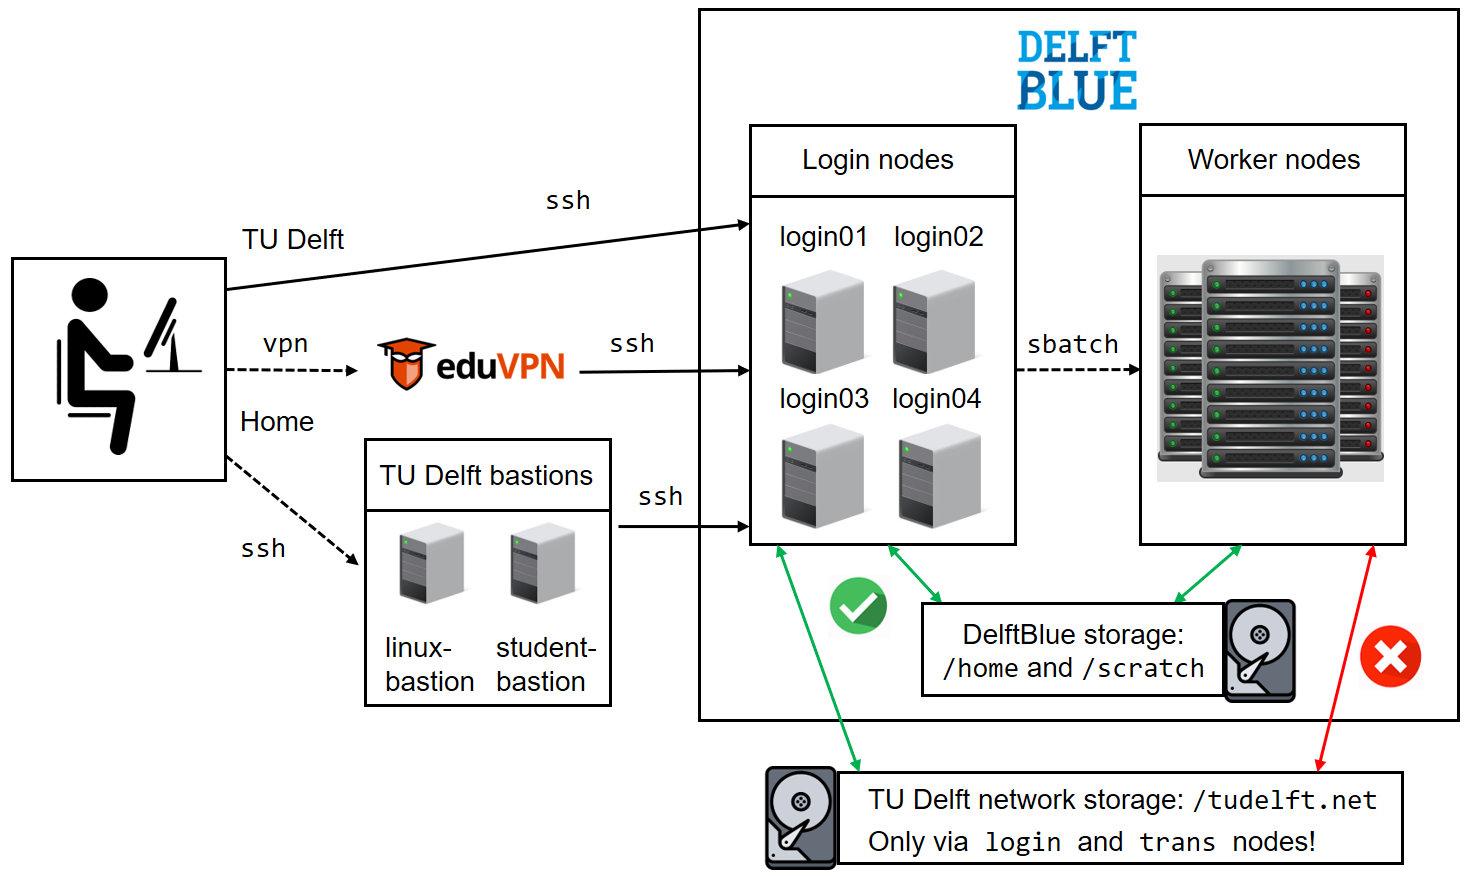
DelftBlue can be accessed with ssh protocol from the university network or by using eduVPN at home.
Upon login you end up on one of the "login nodes", used for setting up your computations (jobs) before they are "submitted" to run on "worker nodes". Login nodes have access to the university-wide network storage, and to the "worker" nodes, where your computations are running.
The chart below shows a basic structure of DelftBlue.
How do I connect?
Open a Terminal on Linux/macOS or Command Prompt on Windows. Type the following command:
Press Enter, you will be asked to enter your NetID password:
Please note, that you will not see any characters appearing on the screen as you type your password. This is normal, and is designed to increase security, so that people watching over your shoulder don't even know how many characters your password contains. Once you typed in your password, press Enter again. You should see the following:
    ____       ________  ____  __
   / __ \___  / / __/ /_/ __ )/ /_  _____
  / / / / _ \/ / /_/ __/ __  / / / / / _ \
 / /_/ /  __/ / __/ /_/ /_/ / / /_/ /  __/
/_____/\___/_/_/  \__/_____/_/\__,_/\___/

Last login: Fri Sep  4 14:06:27 2026 from 145.90.36.181

Authorized users only. All activity may be monitored and reported.

    diskquota    ||           size          ||    chunk files
 location |  id  ||    used    |    hard    ||  used   |  hard
----------|------||------------|------------||---------|---------
 /scratch |    1 ||    6.15GiB |    5.00TiB ||   26988 | 1000000
 /home    |    2 ||    7.45GiB |   30.00GiB ||  139455 | 1000000

[<netid>@login03 ~]$
Please note that a direct ssh to DelftBlue from outside of the university network is impossible! For access from outside of the university network, your best option is to use eduVPN.
More information on how to establish remote connection to DelftBlue can be found here.
Once you are connected, you can start working in your /home/<netid> directory to keep scripts and configuration files,
and some software you may need to install in addition to our software stack.
Your /home directory has a limit of 30GB. For temporary storage of larger amounts of data, you can use your /scratch/<netid> directory. Your /scratch directory has a limit of 5TB, but anything you place there will be cleaned up automatically after 6 months, and is not backed up.
For permanent storage of larger amounts of data, we recommend using TU Delft Project Drives.
How do I transfer files to/from DelftBlue?
The simplest way to transfer your files to and from DelftBlue is to use the scp command, which has the following basic syntax:
For example, to transfer a file from your computer to DelftBlue:
user@laptop:~$ scp mylocalfile <netid>@login.delftblue.tudelft.nl:~/destination_folder_on_DelftBlue/
To transfer a folder (recursively) from your computer to DelftBlue:
user@laptop:~$ scp -r mylocalfolder <netid>@login.delftblue.tudelft.nl:~/destination_folder_on_DelftBlue/
To transfer a file from DelftBlue to your computer:
To transfer a folder from DelftBlue to your computer:
user@laptop:~$ scp -r <netid>@login.delftblue.tudelft.nl:~/origin_folder_on_DelftBlue/remotefolder ./
More information on data transfer and storage on DelftBlue can be found here.
How do I work with DelftBlue?
On a supercomputer, you do not run your program directly. Instead you write a job (submission, batch) script containing the resources you need and the commands to execute, and submit it to a queue via the Slurm workload manager with an sbatch command:
A typical job script looks as follows:
#!/bin/bash

#SBATCH --job-name=job_name
#SBATCH --partition=compute
#SBATCH --account=research-eemcs-diam
#SBATCH --time=01:00:00
#SBATCH --ntasks=4
#SBATCH --cpus-per-task=1
#SBATCH --mem-per-cpu=1GB

module load 2026 cpu
module load openmpi
srun ./executable > output.log
A quick explanation of what each line means:
| Line | Purpose |
|---|---|
#!/bin/bash |
system info: type of script |
#SBATCH --job-name=job_name |
select job name |
#SBATCH --partition=compute |
select partition to run your job on |
#SBATCH --account=research-eemcs-diam |
specify account |
#SBATCH --time=01:00:00 |
request run time |
#SBATCH --ntasks=4 |
number of tasks (parallel) |
#SBATCH --cpus-per-task=1 |
CPUs (threads) per task |
#SBATCH --mem-per-cpu=1GB |
RAM per CPU |
module load 2026 cpu |
use DelftBlue software collection |
module load openmpi |
load openmpi module |
srun ./executable > output.log |
start tasks with srun |
Please note that DelftBlue has a lot of software pre-installed, available via Module System. All you need to do is load required module with the following command:
Once the job finished running, an output file slurm-XXXX.out will be generated alongside with any output files generated by your code.
The most frequently used commands with the Slurm manager are the following three:
sbatch- submit a batch scriptsqueue- check the status of jobs on the systemscancel- cancel a job and delete it from the queue
More information on the Slurm workflow manager on DelftBlue can be found here.
Practical example: running a parallel Python script
Let's say we want to run a little Python program to calculate number pi called calculate_pi.py:
from mpi4py import MPI
from math   import pi as PI
from numpy  import array

def comp_pi(n, myrank=0, nprocs=1):
    h = 1.0 / n
    s = 0.0
    for i in range(myrank + 1, n + 1, nprocs):
        x = h * (i - 0.5)
        s += 4.0 / (1.0 + x**2)
    return s * h

def prn_pi(pi, PI):
    message = "pi is approximately %.16f, error is %.16f"
    print  (message % (pi, abs(pi - PI)))

comm = MPI.COMM_WORLD
nprocs = comm.Get_size()
myrank = comm.Get_rank()

n    = array(0, dtype=int)
pi   = array(0, dtype=float)
mypi = array(0, dtype=float)

if myrank == 0:
    _n = 20 # Enter the number of intervals
    n.fill(_n)
comm.Bcast([n, MPI.INT], root=0)
_mypi = comp_pi(n, myrank, nprocs)
mypi.fill(_mypi)
comm.Reduce([mypi, MPI.DOUBLE], [pi, MPI.DOUBLE],
            op=MPI.SUM, root=0)
if myrank == 0:
    prn_pi(pi, PI)
Here is a step-by-step tutorial of how to run this on DelftBlue.
1. Create a Python code file calculate_pi.py:
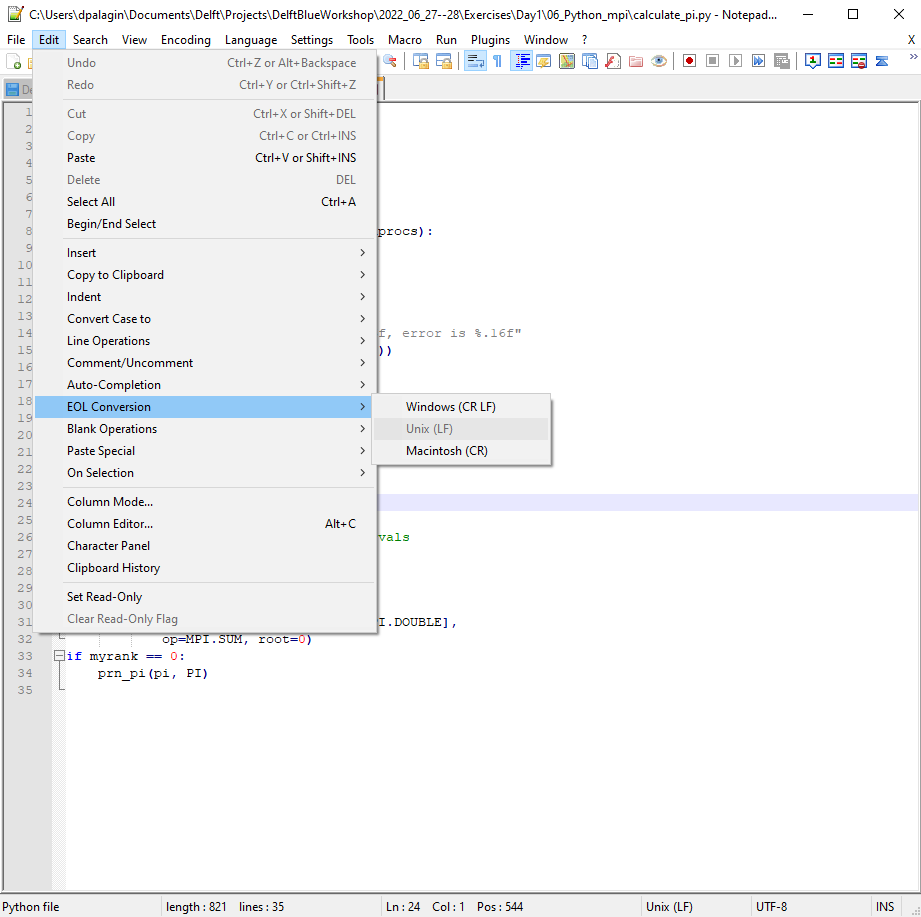
You can just type (copy-paste) the above code in your favourite text editor. Please be aware: Windows and Linux have different "end of line" conventions. This means that if you copy a script created under Windows, it might not be able to run on DelftBlue. Luckily, many text editors actually let you define which end-of-line convention to use. For example, if you are on Windows, we recommend using Notepad++. Then you can use the menu Edit -> EOL Conversion -> Unix (LF) to convert your Windows created script into the format that DelftBlue can easily understand.
2. Create a job (submission, batch) script my-first-job-script.sh:
Same procedure, this time you need to type up the commands to let DelftBlue know what resources to use, and which program to run. Your job script should look as follows:
#!/bin/bash

#SBATCH --job-name="Py_pi"
#SBATCH --time=00:10:00
#SBATCH --ntasks=8
#SBATCH --cpus-per-task=1
#SBATCH --partition=compute
#SBATCH --mem-per-cpu=1GB
#SBATCH --account=research-<faculty>-<department>

module load 2026 cpu
module load openmpi
module load python
module load py-numpy
module load py-mpi4py

srun python calculate_pi.py > pi.log
Let's take a closer look at each command:
The first line of the script is a system line:
#!/bin/bashis a system command, which essentially tells the computer which language the job script is written in. This should be the first line in all your job scripts.
This is followed by the Slurm flags:
#SBATCH --job-name="Py_pi"This is the name of your job. You can type anything you like there.#SBATCH --time=00:10:00This is the time your job is expected to run in HH:MM:SS. Here, we ask for 10 minutes.#SBATCH --ntasks=8This is the number of processes your software will be able to execute in parallel. In a typical case of MPI-parallelism, and provided that the--cpus-per-taskis set to1(see below), this effectively corresponds to the total number of CPU cores you are requesting. Here, we ask for 8 CPU cores.#SBATCH --cpus-per-task=1This is the number of threads the program can allocate per process ('task') (see the flag above). Unless you are dealing with shared-memory parallelism via e.g. OpenMP, keep this flag's value at1.#SBATCH --partition=computeThis is the "partition" of DelftBlue you want your job to run on, which determines the type of resources available.#SBATCH --mem-per-cpu=1GBThis is the amount of RAM we need. Here, we request 1GB of RAM per CPU core.#SBATCH --account=innovationThis is your account. Theinnovationaccount is available for all users and is therefore a good first choice.
After that, we need to load necessary DelftBlue Software Stack modules. Our little program relies on following software being available: Python, numpy, mpi4py. In order to load all these, we will need:
module load 2026 cpuThis is DelftBlue's software collection. Most of other modules rely on this. Since the2026stack, you need to specifycpuorgpualongside the year, depending on whether your job runs on regular compute nodes or GPU nodes; this example uses--partition=compute, socpuis used.module load openmpiThis module enables parallelisation tools.module load pythonThis module enables Python 3.13.12.module load py-numpyThis module enablesnumpy.module load py-mpi4pyThis module enablesmpi4py, a package needed to run Python in parallel. This module relies onopenmpibeing loaded already.
Finally, we tell the computer what to actually run:
srun python calculate_pi.py > pi.logThis startspythonusingcalculate_pi.pyas an input file, and its output is redirected to a file calledpi.log. Please note, that you have to start this line withsrun, a program which enablesSlurmto access the requested resources correctly. In this example, we requested 8 "tasks", sosrunwill start 8 instances of python that can communicate via MPI. Each instance will be allowed to use one CPU core, i.e., run a single thread.
Now we are ready to copy these two files to DelftBlue.
3. Open a new Command Prompt window. Connect to DelftBlue:
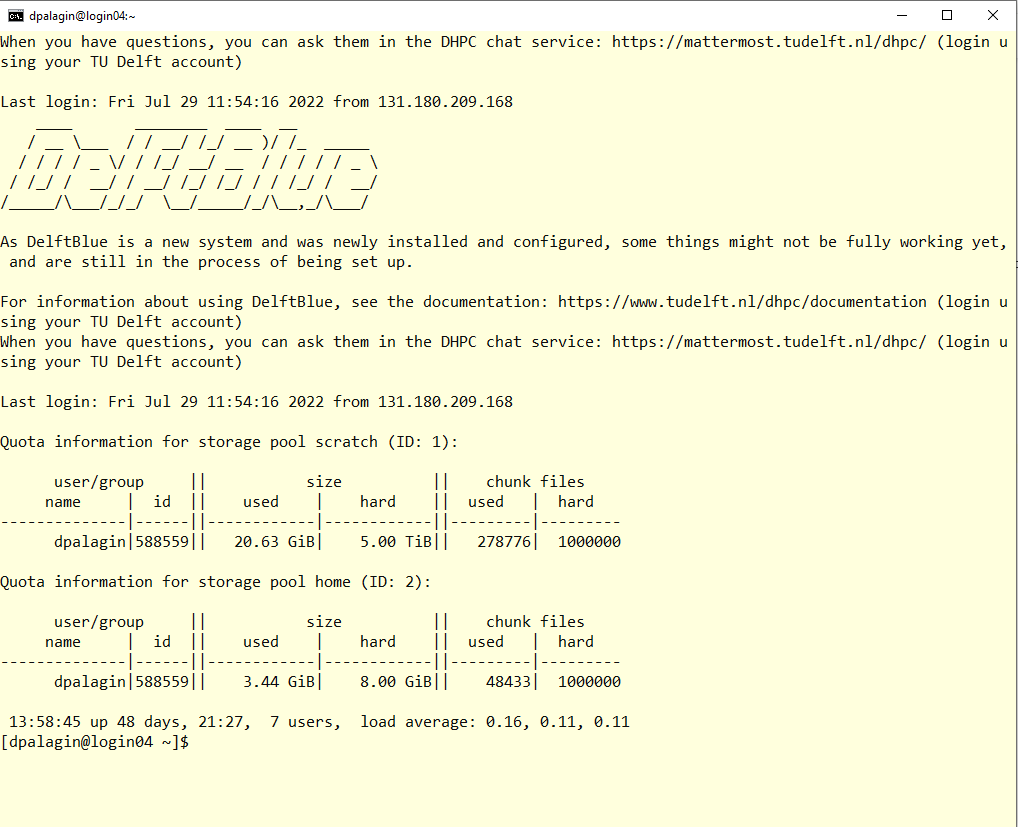
Keep this instance (window) of the Command Prompt open. Once you are connected to DelftBlue, this is you DelftBlue terminal:
4. Change to /scratch, create a new folder on DelftBlue, where you will submit your job from, and change to that folder:
[<netid>@login04 ~]$ cd /scratch/<netid>
[<netid>@login04 <netid>]$ mkdir my-first-python-job
[<netid>@login04 <netid>]$ cd my-first-python-job
5. Now open another instance (window) of Command Prompt.
This will be your local (Windows) command line:
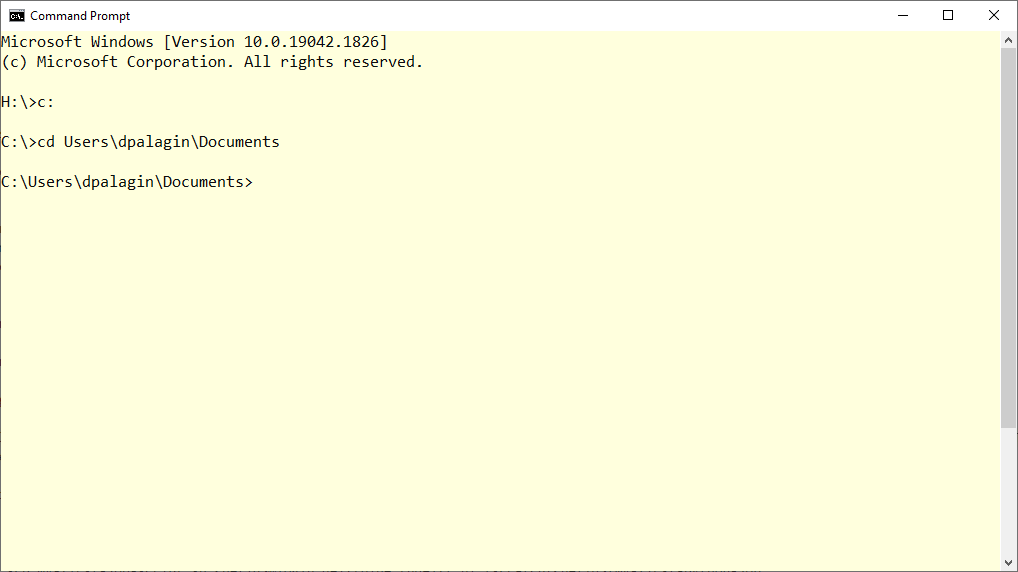
We will use this to copy files to and from DelftBlue. Please note that you can only initiate file transfer from your local computer, not from DelftBlue itself. This is because your local computer does not have a network address that DelftBlue can recognise.
6. Copy both calculate_pi.py and my-first-job-script.sh to DelftBlue:
C:\Users\<netid>\Documents> scp calculate_pi.py <netid>@login.delftblue.tudelft.nl:/scratch/<netid>/my-first-python-job
C:\Users\<netid>\Documents> scp my-first-job-script.sh <netid>@login.delftblue.tudelft.nl:/scratch/<netid>/my-first-python-job
Now go back to your DelftBlue terminal.
7. Submit your job:
You can now see your job running in the queue:
[<netid>@login04 my-first-python-job]$ squeue --me

             JOBID PARTITION     NAME     USER ST       TIME  NODES NODELIST(REASON)
            839272   compute    Py_pi  <netid>  R       0:02      1 cmp019
Once the job is finished, you see two new files created in your folder:
[<netid>@login04 my-first-python-job]$ ls

calculate_pi.py  my-first-job-script.sh  pi.log  slurm-839272.out
You can see the contents of each file with, for example, cat command:
The slurm-839272.out file contains system messages, such as notifications about modules that were loaded automatically for you as dependencies, or warnings and error messages. In this case, the file is empty, meaning there were no errors or system messages to report.
What about the pi.log? Let's see:
[<netid>@login04 my-first-python-job]$ cat pi.log

pi is approximately 3.1418009868930938, error is 0.0002083333033007
This is the expected output of the Python script.
Now switch to your local (Windows) command line again:
8. Copy your results back to your computer:
C:\Users\<netid>\Documents> scp <netid>@login.delftblue.tudelft.nl:/scratch/<netid>/my-first-python-job/*.* ./
This will copy all of the files in /scratch/<netid>/my-first-python-job directory back to your computer.
Congratulations, now you know how to use DelftBlue and you just ran your first (parallel!) job on a supercomputer. Do not forget to read the Documentation, and to ask questions on Mattermost. Happy Computing!